Main Menu
  • Home
  • Services
    • Strategy
      • Technology Partner
      • UI / UX
      • Technology Due Diligence
      • Why Projects Succeed
      • What Software Costs

      Core Technologies
      • PHP
      • JavaScript
      • Laravel
      • VueJs
      • AWS
    • Development
      • Software Development
      • Mobile App Development
      • Software Integration
      • Hardware Integration
      • Software Support (SLA)
      • Software Takeover
      • Managed Hosting
      • Microsoft Access Databases
      • Replace Spreadsheets
    • AI
      • AI for Business
      • AI Reporting
      • Private AI Hosting
      • On-Premise AI
    • Industries
      • Manufacturing
      • Transport / Logistics
      • Finance
      • Retail & E-commerce
      • Government
      • Construction
      • Health
      • Insurance
      • Mining
  • Our Work
  • About
  • Blog

© 2020 Codium Pty Ltd.

Codium Logo Codium Logo
  • Services
    • Strategy
      • Technology Partner
      • UI / UX
      • Technology Due Diligence
      • Why Projects Succeed
      • What Software Costs

      Core Technologies
      • PHP
      • JavaScript
      • Laravel
      • VueJs
      • AWS
    • Development
      • Software Development
      • Mobile App Development
      • Software Integration
      • Hardware Integration
      • Software Support (SLA)
      • Software Takeover
      • Managed Hosting
      • Microsoft Access Databases
      • Replace Spreadsheets
    • AI
      • AI for Business
      • AI Reporting
      • Private AI Hosting
      • On-Premise AI
    • Industries
      • Manufacturing
      • Transport / Logistics
      • Finance
      • Retail & E-commerce
      • Government
      • Construction
      • Health
      • Insurance
      • Mining
  • Our Work
  • About
  • Blog
AI for business · On-premise AI

AI that runs on hardware you own, in a rack you can point to.

For some organisations, "hosted in Australia" still isn't close enough. We specify, supply and set up local inference hardware, from a single AMD AI workstation with 128GB or more of unified memory to NVIDIA RTX PRO Blackwell rack servers, running open-weight models through vLLM. Installed on your premises or in an Australian colocation facility, and managed by us for as long as you need.

Talk about a local setup The hardware
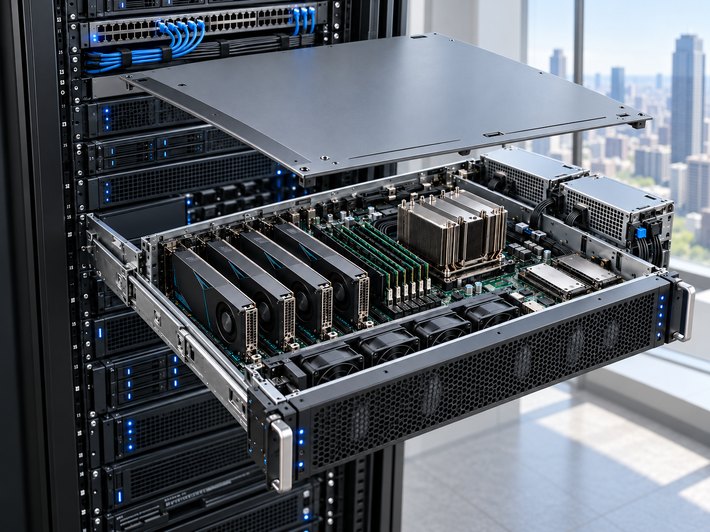
A 2U GPU inference server slid out of a rack with its lid off, showing four GPUs, memory, CPU, fans and redundant power supplies
  • Your hardwareWorkstations, GPU servers or a full rack, specified for your workload and owned outright.
  • Your premises or coloInstalled in your server room, or in an Australian colocation facility we arrange and manage.
  • Open-weight modelsLlama, Qwen, Mistral, Gemma, DeepSeek and OpenAI's open-weight models, served through vLLM.
  • Run by usSet up, monitored, patched and tuned by the same team that runs our managed hosting.
Why local?

When the data can't leave, or the token bill has stopped making sense

Cloud inference is the right answer for most businesses, and we set that up in Australia too. Local hardware is for the cases it can't cover: data that must stay on your network by policy or contract, sites with poor or restricted connectivity, and workloads where a steady, heavy volume of tokens makes owning the hardware cheaper than renting it per request.

"Where does the model actually run?"

  • ×Data leaves your network to be processed, even if it stays in-region

    ✓Prompts and documents never leave your network

  • ×Billed per token, forever, scaling with how useful it becomes

    ✓Hardware bought once, power and management as the only running cost

  • ×Models, rate limits and pricing change on the provider's schedule

    ✓You pick the model and the version, and change it when you choose

  • ×Needs an internet connection on every request

    ✓Works on an isolated network, a mine site or a ship

Air-gap if you need to

The whole stack runs without internet access once it's installed. Model weights, the serving layer and the chat interface all live on your hardware.

Predictable cost at volume

A workstation that serves a team all day costs about the same as a few months of heavy API use. We'll show you the crossover for your workload before you buy anything.

Sized to the job

A unified-memory workstation runs 70B-class models for a small team. A pair of RTX PRO Blackwell cards serves a 30B model to a department. A rack serves the company.

Same API as the cloud

vLLM exposes an OpenAI-compatible endpoint, so software written against cloud models points at your server with a one-line change, and can fall back the other way.

The hardware

Three sizes, from a box under the desk to a rack in a data centre

We specify from the models and the number of concurrent users you need, not from a catalogue. Most builds fit one of the three below.

01

AMD AI workstation, unified memory

A compact workstation built on AMD's Ryzen AI Max processors, where CPU and GPU share one large pool of unified memory, 128GB on the current generation and growing with each one. That's enough to hold a 70B-class model, or a 30B model with a long context, on a machine that plugs into a standard power point and sits quietly under a desk or in a comms cupboard. The right starting point for a team of five to twenty.

128GB+ unified memory70B models at 4-bitSingle power pointTeams up to ~20
02

NVIDIA RTX PRO Blackwell servers

Rack-mount servers with one to four NVIDIA RTX PRO Blackwell GPUs, chosen from the range to match the models and the number of users. vLLM shards a model across them and batches requests, so a department gets fast, concurrent inference from a 2U box.

RTX PRO Blackwell range1 to 4 GPUsRack mount
03

Full rack and colocation

Multiple GPU nodes behind a load balancer, with redundant power and networking, in your data centre or an Australian colocation facility we arrange.

04

vLLM serving layer

High-throughput serving with continuous batching, paged attention and quantised weights, behind an OpenAI-compatible API your software already speaks.

05

Models you choose

Llama, Qwen, Mistral, Gemma, DeepSeek and OpenAI's open-weight models, picked and quantised for your hardware, swapped when something better ships.

06

Access, logging and monitoring

A gateway in front of vLLM handles single sign-on, per-team access, rate limits and request logging, with GPU utilisation, latency and queue depth on a dashboard our team watches.

How we run environments

Not sure local is the right call?

Often it isn't, and the honest answer is a managed setup in AWS Sydney with the same controls. We'll size both against your workload and tell you which one we'd choose.

Compare with private AI hosting
How it works

From workload to a server your staff are using

We do the whole thing: sizing, procurement, build, installation and the running of it afterwards. You end up with hardware you own and a team that knows how to use it.

01

Size

Which models, how many users at once, what context lengths, and what the data rules are. From that we specify the hardware and show you the cost against a cloud equivalent.

02

Build

We procure or you procure, then we build and burn in the machine: OS, drivers, vLLM, the model weights, the gateway and monitoring, tested under load before it leaves our bench.

03

Install

Racked in your server room or in a colocation facility we arrange, connected to your network and identity provider, with the chat interface and API live for your team.

04

Run

Monitoring, patching, model updates and capacity reviews from our hosting team, with the option to hand it all over to your own IT team with documentation and training.

Under the hood

vLLM, quantised weights and a gateway you control

A laptop demo serves one person. A server for a department needs a serving layer, and vLLM is the one that lets a GPU answer many people at once without falling over.

  • Continuous batching. Requests from many users are batched on the fly, so throughput scales with concurrency instead of queueing.
  • Quantisation. 4-bit and 8-bit weights fit larger, better models into the memory you have, with accuracy we test before we ship.
  • Tensor parallelism. One model split across several GPUs when it's too big for one, transparent to the caller.
  • OpenAI-compatible API. Chat, completions and embeddings endpoints that existing software and SDKs already know how to call.
  • Gateway and logs. SSO, per-team keys, rate limits and request logging in front, with Prometheus and Grafana behind, all on your network.
Putting the models to work in your software
Monitoring dashboard showing GPU and request metrics Monitored from our ops desk
Who it's for

Where local inference is the right tool

Government and defence supply chain

Classified or caveated data that cannot be processed by any third party, cloud included, with the hardware inside an accredited facility.

Health and research

Patient records and research data under ethics approvals that name where processing may occur, served from the hospital or university's own racks.

Remote and disconnected sites

Mines, vessels, regional operations and industrial sites where connectivity is slow, metered or deliberately cut off from the internet.

High-volume software products

Platforms running millions of tokens a day through document reading, classification or extraction, where per-token pricing has become the biggest line on the bill.

Good questions

Things people ask before they buy a GPU

Can't see yours? Ask us directly.

Are open-weight models good enough?

For most business tasks, yes. Current open-weight models from Meta, Alibaba, Mistral, Google, DeepSeek and OpenAI handle summarisation, drafting, extraction, classification and question answering over your documents well. The frontier models in the cloud are still ahead on the hardest reasoning, which is why we often pair a local server with a hosted fallback for the few requests that need it.

What can a unified-memory workstation actually run?

With 128GB of unified memory, a 70B-class model at 4-bit quantisation with room for context, or a 30B model at higher precision with long context. Each new generation lifts that ceiling. It will serve a small team comfortably. It is not a replacement for a multi-GPU server when forty people hit it at once, and we'll tell you which side of that line you're on.

Why RTX PRO Blackwell cards rather than a bigger GPU?

The RTX PRO Blackwell range runs on standard server power and cooling, and several of them fit in an ordinary 2U chassis. For serving quantised 30B to 70B models to a department, a few of them is usually a better fit than one very large, very hot card, and we pick the card in the range that suits the workload. When a workload genuinely needs more, we specify more.

Who owns the hardware and where does it live?

You do. It lives in your server room, or in an Australian colocation facility where we arrange the rack space, power and connectivity and manage it on your behalf. Either way it's your asset, and you can take over running it whenever you want.

Can our existing software use it?

If it calls an OpenAI-style API, it points at your server with a configuration change. If it doesn't yet, that's the kind of integration we build: document reading, answering from your data, drafting from your records, all against the local endpoint.

What happens when a better model comes out?

We test it on your hardware, check it against your workload, and swap it in during a maintenance window if it's an improvement. The hardware and the API stay the same, so your software doesn't notice.

Want AI that never leaves the building?

Tell us the models you have in mind, how many people would use it and where it would live. We'll come back with a specification, a price and an honest comparison with the hosted alternative.

Get in touch Private AI hosting instead
Codium Logo
Codium Pty Ltd.
Ground Floor, 207 Greenhill Road
Eastwood, 5063
Adelaide, South Australia

Company

  • About us
  • Industries
  • Why Projects Succeed
  • What Software Costs
  • Blog
  • Terms of Business
  • Customer Experience
  • Quality Policy
  • Security Policy
  • Privacy Policy

Services

  • Software Development
  • Mobile App Development
  • AI for Business
  • Support Services
  • Software Takeover
  • Replace Spreadsheets
  • Managed Hosting
  • Software Integration
  • Technology Partner
  • Technology Due Diligence
  • Microsoft Access

Support

  • Contact Us
  • Customer Feedback
  • Careers
  • Codium Remote Support

Socialise

© Codium Pty Ltd. All Rights Reserved.

Back Top